
In Good Character: Designing an Ingestion Pipeline for Hostile Tabletop Rules
New to this series? Open for context
Engineering the Rules Oracle
Modern tabletop games rely on fragmented rulebooks, supplements, and changing FAQs. The Rules Oracle is a hosted Q&A engine built to return cited, page-referenced answers to complex rules questions. This series covers the engineering behind it.
Access is currently invite only during the beta period.
- Part 1: In Good Character: Designing an Ingestion Pipeline for Hostile Tabletop Rules ← you are here
- Part 2: Pulling Rank: Using Fused Retrieval to Bridge the Alias Gap
- Part 3: Fielding Questions: Using JSON Constraints to Force Grounded Answers
- Part 4: Preventing RAG Regressions: Eval Harnesses and Production Gates
Building a system that a “Rules Lawyer” can actually trust is an exercise in defensive engineering. If the system hallucinates a rule or cites the wrong page, you get a wrong ruling at the table and trust in the Oracle drops fast.
That is why I did not start with a clean, digital native PDF. I picked a tabletop wargame I already owned and used it as a validation corpus The complete set of source documents ingested, chunked, and indexed for retrieval — here, the PDF rulebooks for a game system. The corpus is swappable; the pipeline architecture is not. : not the worst rulebook set in existence, but one that checked a lot of boxes at once. The books were originally translated from French. The PDFs I have are scans, not publisher masters, and the quality varies page to page. One volume has pages scanned upside down. There are tables, artistic side sections, and battleboards where custom dice symbols sit above abilities with nonsense names and dense rules text. Distances are marked with symbols, not spelled out. No single page is impossible. Taken together, it is an angry, sleep-deprived tween My wonderful daughter Natalie. of a corpus. If the pipeline handles that mix honestly, I can trust it on cleaner books later.
What “Structural Truth” Actually Means
That corpus needed a bar for success sharper than “the embeddings A numeric vector that represents text meaning in a high-dimensional space. Similar passages land near each other; unlike wording can still cluster if the concepts overlap. Dense retrieval compares a question embedding against chunk embeddings to find semantic neighbors. look fine.” I call it Structural Truth: three guarantees on every chunk A retrieval-sized slice of source text: one rule section, table, ability cell, or similar unit, usually with metadata (heading path, page number) attached. Chunks are what get embedded, searched, and passed into the answer model — not whole PDFs. that leaves ingest.
- Heading path — the chunk knows where it lives in the book.
- Icon meaning in text — glyphs and distance symbols on the page show up as searchable text, not invisible decoration.
- Book page number — the footer number the player sees, not PDF file order.
A clean digital document earns those for free with text extraction. This corpus does not. The ingest CLI’s manifest math uses about $0.005 per page for Claude Haiku vision parse. A 200 page book cold runs roughly $1.00 in vision fees alone (embeddings add pennies). Each page waits on its own API round trip, plus ImageMagick render time when the cache misses. Seconds per page, not milliseconds.
If the data foundation is fractured, the rest of the stack is built on sand. Retrieval can get smarter forever and still lose on citation day one.
The Pivot: From Text Extraction to Vision Parse
The hosted Oracle did not start here. It started where most RAG A pattern where a language model answers using retrieved document chunks instead of parametric memory alone. Retrieval grounds the answer in your corpus; generation turns those chunks into natural-language responses (ideally with citations). prototypes start: grab the text layer and hope for the best.
The Prototype: unpdf
In my earlier local experiment (the “Rules Lawyer,” which I wrote about in Structure Before Semantics), I used unpdf. It worked under tight constraints. I always knew that moving to a hosted, production ready stack would require me to parse ways with the tool.
unpdf reads the PDF text layer and nothing else. Against the validation corpus above, that is not enough. That was fine for a free tier prototype. It was not fine for a tool people would rely on at the table.
So I lifted the constraints and moved to hosted APIs. That is where the real ingest story begins.
Attempt One: Google Document AI (The Legacy Brain Trap)
Document AI was my first hosted move. Layout aware OCR Optical Character Recognition: software that turns pixels in a scan or photo into machine-readable text. Layout-aware OCR also tries to preserve structure (headings, columns, tables). On hostile PDFs, OCR quality varies page to page and is often why naive text extraction fails. and paragraph detection: a massive step up from raw text extraction.
I still walked into a trap I call Legacy Brain.
The mistake was architectural, not API choice. I wanted every stage of the pipeline to be provider agnostic, but I had not drawn a clean boundary around provider specific logic. Document AI already returned layout aware paragraphs and style metadata. I was still doing manual work in the main ingest path to infer page numbers and reconstruct hierarchies: work that only existed because the unpdf prototype had no layout model.
That cleanup code belonged inside the Document AI provider. Instead it leaked into shared pipeline code. I spent days writing workarounds for problems the new API had already solved, simply because I had not updated my mental model to trust the new data source.
Even after I cleaned up the architecture, Document AI still failed on the worst pages in the validation set: the battleboards and symbol heavy spreads. I needed something that treated the page as a layout problem, not a text stream problem.
Attempt Two: Vision Parse via Claude Haiku
The production pipeline uses Claude Haiku 4.5 through a VisionParseProvider. The shift was simple on paper: stop trusting the PDF text layer, start trusting what the page looks like.
Here is the order of operations, end to end:
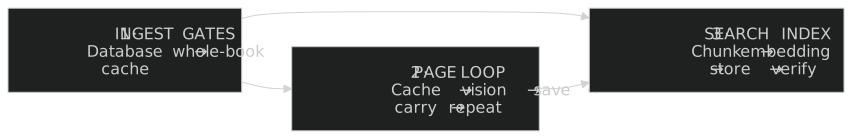
Read it outside-in. The database gate skips files you have already ingested. The whole-book parse cache skips the entire page loop (no Anthropic calls). Inside a parse miss, each page checks its own cache before rendering. On a miss: render, extract, save, then carry context forward. That save before advance step matters. If page 87 fails, pages 1–86 are not lost work.
Chunk is the step that turns structured pages into retrieval-sized pieces: one chunk per rule section, table, or ability cell, inheriting the heading path from parse. It runs every ingest even when parse is cached, because chunk logic can change without re-parsing the PDF.
The model does not return freeform prose. It must populate an extract_page schema: sections with heading levels, contentType labels (rule, ability, stats, table, and others), table rows when isTable is true, and continuation flags when content spans a page break. Downstream chunking consumes that shape directly.
That schema, plus the per page loop, is how the pipeline delivers Structural Truth:
- Guarantee 1 (heading path) — section hierarchy in the schema, with rolling context so rules that span pages stay attached to the same heading stack. Battleboards map to “ability grids” in the prompt: one section per cell, not one blob for the whole grid.
- Guarantee 2 (icons in text) — the prompt instructs the model to write glyph meanings inline. There is no separate symbol validator in code today; fidelity depends on prompt discipline and post ingest checks on page coverage and chunk shape.
- Guarantee 3 (book page) — the schema includes a
bookPagefield read from the printed footer. Scan quirks (blur, rotation) are why that field comes from vision, not file order alone.
One operational gotcha: the cache key for each page includes a hash of the rolling context, plus file hash, page index, model id, and prompt version. A correction on page 42 invalidates page 43 and everything after it. I accept that cost so cross page rules stay structurally honest.
The Economics of Ingest: Why Caching is Mandatory
Understanding is expensive. Storage is cheap. Production can absorb a dollar per book once. Development cannot absorb it every time you rename a chunk field. At that price, I had to keep a close eye on my cache flow.
Versioned, incremental caching is not an optimization here. It is a core architectural requirement. The diagram above maps to four gates:
- Already in the database? — skip unchanged files at corpus scan time.
- Whole book already parsed? — skip the entire page loop; this is what makes re-chunking free.
- This page already parsed? — skip render and API for individual pages during a partial re-run.
- Embeddings already computed? — skip OpenAI within a single ingest run when chunk text has not changed.
Front load the expensive understanding at ingest, and everything downstream gets cheaper to iterate. Chunk boundaries, embedding models, retrieval prompts: all of that can move freely as long as the frozen parse output stays the same. The book-level and page-level parse caches are the assets you keep.
Conclusion: Front Loading Structural Truth at Ingest
Building a high fidelity RAG system is a game of shifting complexity. I could have settled for a cheaper, simpler ingestion path. I would have paid for it later with unreliable citations and endless prompt tuning.
Instead I front loaded engineering at the ingest stage. Part 1 buys the rest of the stack a parse layer that outputs section shaped data with Structural Truth baked in, not a bag of sentences. Retrieval still has hard problems ahead. It is not starting from layout lies.
When a user asks a question, the Oracle is not pattern matching on a “vibe.” It is searching chunks whose structure was fixed at ingest time. We traded initial compute and latency for long term consistency, which keeps query time fast and cheap where it matters: at the moment a player needs an answer.
Clean data is only the first layer. Rulebooks are living documents, and even the best parser cannot solve the Alias Gap or the Supersession Problem on its own. In Part 2: Retrieval, I look at how I built a retrieval engine that handles game updates and synonyms, so the Oracle surfaces the rule that is actually in effect.